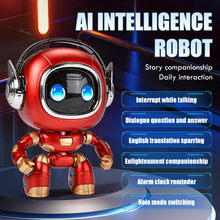
Zibby AI Multilingual Storytelling & Learning Companion Robot
- Languages Supported37 to 66 Languages
- Core AI EngineChatGPT & DeepSeek Dual-Stack
- Audio ArchitectureFar-Field Dual Mic + AEC
- Order BenchmarkSample MOQ: 1 pc
Assessed supplier integrity & facilities
Strict European & US toy standards
Zero-risk sampling & pilot runs
Firmware, plush, molds & cloud
Why legacy silicon chips with pre-recorded MP3 files are vanishing, and how generative, multilingual voice AI is reshaping consumer demand across 140+ countries.
Global toy sourcing departments, educational distributors, and e-commerce brand aggregators face a pivotal turning point in connected consumer hardware. For more than two decades, the interactive storytelling toy sector was dominated by pre-programmed sound microcontrollers, static optical reader pens, and repetitive MP3 audio tracks hardcoded into ROM chips. When parents and children exhausted the static library of 10 or 20 stories, engagement plummeted to zero, resulting in high return rates, compressed shelf lives, and severe discount pressure on retailers.
The introduction of the modern Multi-Language AI Storytelling Toy has completely disrupted this paradigm. By fusing edge-based acoustic front-ends with ultra-low latency large language models (such as ChatGPT, DeepSeek, and specialized proprietary children's educational engines), these next-generation interactive toys provide non-linear, branching narratives. When a toddler asks, "Why did the dragon leave the castle without his boots in French?", the toy does not throw a generic error prompt. It dynamically crafts an age-appropriate story arc in real time, mirroring pediatric educational pedagogical guidelines while maintaining conversational context.
As a seasoned manufacturing leader based in Shenzhen's electronics ecosystem, Shenzhen Vgoodtoys Technology Co., Ltd. bridges the gap between advanced cloud AI architectures and cost-effective, scalable toy manufacturing. With comprehensive supply chain integration, on-site TÜV Rheinland verification, and CE/FCC compliance, we empower retail partners to launch defensible, brand-differentiated intelligent toys with minimal lead times and unmatched unit margins.
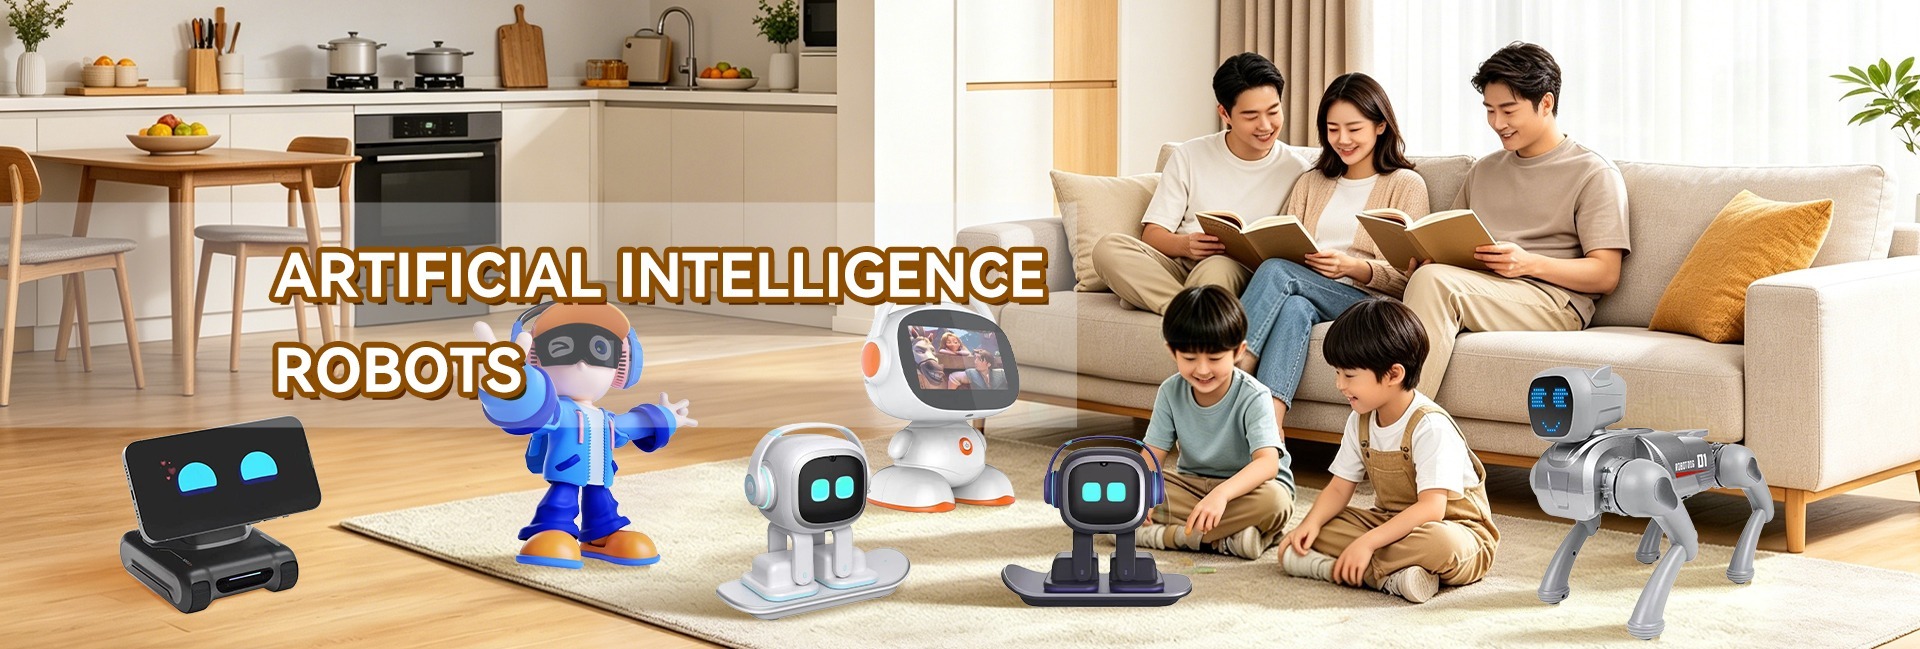
Factory-verified, export-ready intelligent storytelling platforms tested for cross-border compliance, voice recognition accuracy, and consumer durability.


No matching models located. Inquire directly for bespoke hardware designs.
Make data-backed procurement choices. Review how different hardware form factors balance battery life, edge caching, and language flexibility.
| Form Factor / Series | Target Age & Channel | AI Architecture & Latency | Language Localization Capacity | Compliance & Certifications | Sample & OEM Feasibility |
|---|---|---|---|---|---|
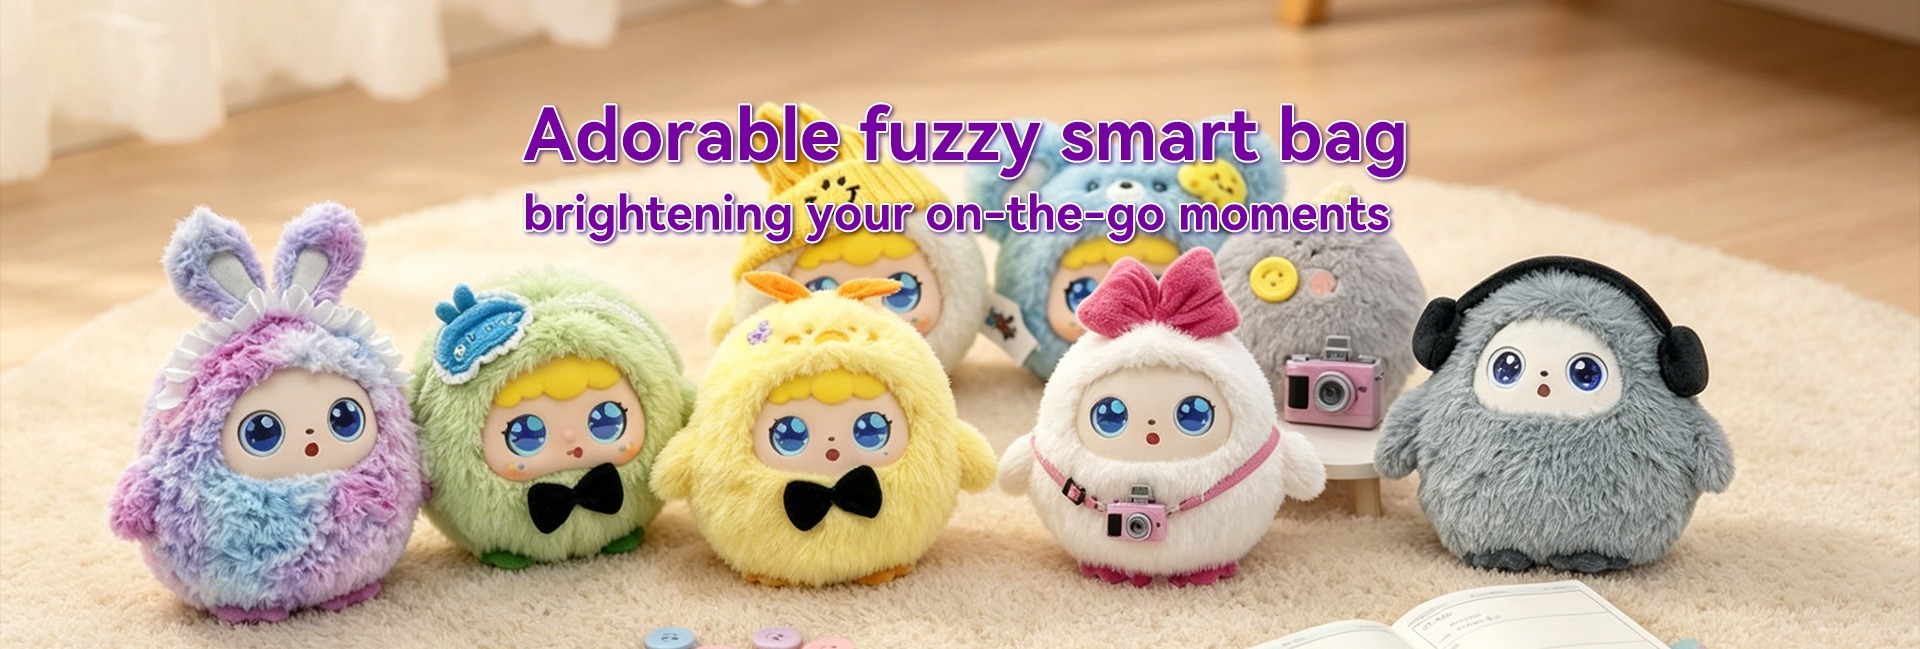
| AI Plush Companion Series | Ages 2-6 | Gift retail, e-commerce, nursery stores | Hybrid cloud TTS with low-power Wi-Fi; latency ~850ms | 37+ standard languages with custom accent tuning | CE, EN71-1/2/3, ASTM F963, Lead & Phthalate Free | MOQ: 1 pc sample; custom embroidery & box from 500 pcs |
| Zibby Educational Robot | Ages 4-10 | STEM programs, bilingual kindergartens | Dual LLM (DeepSeek / ChatGPT), multi-turn reasoning | Up to 66 languages with live translation toggle | CE, FCC Part 15, RoHS, WEEE, RED Directive | MOQ: 1 pc sample; complete firmware branding available |
| Desktop Interactive Pet | Ages 6+ & Teens | Consumer lifestyle, tech boutiques | Visual emotion matrix display + streaming voice TTS | Multilingual prompt library (English, Spanish, French, etc.) | CE, FCC, UN38.3 battery transport safety approved | Standard shells in stock; customized tooling on request |
| Loona-Style AI Robotic Pet | Ages 5-12 | Premium consumer electronics, specialty toy chains | Multimodal sensory inputs (quad-mic, capacitive touch, ToF sensors) | Global dialect recognition with real-time accent parsing | CE-EMC, EN62115 (Electric Toy Safety), RoHS, REACH | Turnkey private labeling and branded mobile app options |
Manufactured and calibrated at Shenzhen Vgoodtoys Technology Co., Ltd. engineering facility in Shenzhen, China.
Navigating cloud operational costs, regulatory crackdowns, and evolving consumer buying habits from 2025 through 2030.
For international sourcing directors and enterprise toy procurement managers, integrating artificial intelligence introduces commercial dynamics far beyond traditional Bill of Materials (BOM) cost calculations. Unlike plastic injection toys whose cost structure concludes once freight reaches destination ports, a modern multi-language AI storytelling toy interacts with external servers throughout its product lifecycle. Buyers navigating orders for 2025 and 2026 must align with several critical industry shifts:
Early AI toys frustrated end-consumers with mandatory monthly API subscriptions, causing severe review attrition on marketplaces like Amazon. Emerging procurement trends favor toys built with pre-allocated cloud token allowances (e.g., 500 hours of active conversational storytelling included in the hardware price), managed via high-efficiency token compression algorithms at the server edge.
Customs and regulatory authorities across the European Union and North America now scrutinize connected children's products with zero tolerance. Importers must only source products that implement ephemeral audio processing: voice data is converted to text, processed through an inference filter, and purged immediately from server RAM without being stored or used for LLM retraining.
Global logistics demand modular physical architectures. Leading buyers prefer designs where the outer character shell (plush rabbit, dinosaur, astronaut robot) can be altered rapidly while preserving a standardized, pre-certified internal electronic core. This slashes safety re-testing costs by over 60% across seasonal product launches.
Generic synthetic voice engines often sound unnatural in regional dialects (e.g., Canadian French vs. Parisian French, Latin American Spanish vs. Castilian Spanish). Future-ready sourcing involves choosing suppliers with neural TTS pipelines capable of adopting native regional cadences that instill emotional trust in young listeners.
Shenzhen Vgoodtoys Technology Co., Ltd. works directly with global importers to pre-configure cloud token routing, ensuring zero unpredictable server bills for your brand. By utilizing localized CDN nodes in Frankfurt, Virginia, and Singapore, our hardware maintains sub-second responsiveness without inflating retail price points.
Hardware-level breakthroughs: small language models (SLMs), neural voice engines, and acoustic beamforming.
Behind every engaging story told by our interactive devices lies a complex chain of acoustic, linguistic, and cognitive computing. As voice AI matures, three technological transformations are defining the next generation of smart storytelling companions:
Total reliance on continuous cloud connectivity has long been the Achilles' heel of connected smart toys. Poor home Wi-Fi or travel environments rendered traditional connected toys completely mute. Next-generation multi-language storytelling toys now utilize lightweight on-device microcontrollers capable of running quantized, offline speech-recognition models and locally cached interactive bedtime scripts. When an active internet connection is available, the device gracefully transitions to cloud-based LLMs for boundless conversational improv, returning seamlessly to local flash memory when disconnected.
Early voice synthesis sounded robotic, monotonous, and incapable of capturing a child's imaginative wonder. Modern conversational hardware leverages dynamic Speech Synthesis Markup Language (SSML) injected on the fly by the storytelling LLM. When the generated narrative features an angry troll or a whispering fairy, the toy automatically modulates its pitch, tempo, and volume, delivering dynamic theatrical performances that match human voice actors.
Young children do not speak with the precise enunciation or rhythm of adult business professionals. They interrupt, mumble, whisper, and speak over loud background toys or television sets. Our engineering team at Shenzhen Vgoodtoys Technology Co., Ltd. incorporates custom dual-microphone arrays with hardware DSP filters tuned specifically to children's high fundamental vocal frequencies (typically 250 Hz to 400 Hz). This enables crystal-clear wake-word triggers and uninterrupted conversational turn-taking even in reverberant family rooms.
Shenzhen Vgoodtoys Technology Co., Ltd. is a high-tech AI products company integrating R&D, precision manufacturing coordination, global sales, and ongoing technical support. Backed by more than five years of hands-on experience in the AI toy industry and deeply anchored within Shenzhen’s world-class consumer electronics supply chain, we deliver one-stop intelligent toy solutions to importers, wholesale distributors, and brand owners across the globe.
Our engineering division blends electronic hardware expertise with robust export know-how. We provide flexible customization spanning voice firmware, custom wake-words, proprietary companion app development, physical injection tooling, and bespoke plush exterior design. Our low-barrier MOQ policy starting from 1 piece enables retail brands to validate regional consumer demand before committing capital to full mass production runs.


Physical plant capacity, trade legitimacy, and production facilities rigorously inspected onsite.
Strict European Union electrical safety, radio frequency, and electromagnetic compatibility verified.
Audited trading status with verified financial settlement across 9 world currencies.
Toxicological non-toxicity, drop test resistance, and choke hazard elimination engineered into every SKU.
Technical, operational, and commercial answers to the critical questions B2B importers ask before placing purchase orders.
Voice response lag is the single largest factor affecting child engagement. If a child speaks to a toy and waits more than 2 seconds for a response, the conversational illusion breaks completely. At Shenzhen Vgoodtoys Technology Co., Ltd., we tackle latency through a multi-tier pipeline: on-device voice activity detection (VAD) instantly catches speech termination, streaming audio chunks directly to regionally distributed cloud edge nodes (e.g., AWS US-East, Frankfurt for Europe, and Singapore for Southeast Asia).
Our server architecture leverages optimized streaming text-to-speech (TTS), enabling the toy's audio speaker to begin vocalizing the introductory sentence while the remainder of the LLM's story response is still generating in memory. This compresses overall round-trip turnaround times to between 600ms and 950ms under normal Wi-Fi conditions.
Child safety and personal identifiable information (PII) protection are non-negotiable for North American and European imports. Our toys adhere to an ephemeral zero-data retention framework: the toy does not store child audio recordings either locally or on the cloud.
Audio is ingested through encrypted TLS 1.3 streams directly into RAM, processed purely to generate the immediate text narrative, and instantly flushed. No biometric voiceprints, geographic coordinates, or personally identifiable profiles are retained or sold. Furthermore, our products do not include hidden camera hardware unless expressly contracted under parent-gated monitoring provisions.
We provide two flexible business models for API token consumption:
Option A (Turnkey Factory Cloud): Each unit comes pre-bundled with an estimated 1 to 2 years of active story usage backed by our server infrastructure, built into the base FOB price so retailers incur zero subscription headaches.
Option B (Client Bring-Your-Own-Key): For enterprise clients with existing OpenAI, Anthropic, or DeepSeek cloud enterprise agreements, our engineering team configures the toy’s companion app and device firmware to communicate directly with your private cloud endpoint, allowing you to control API costs and manage backend telemetry independently.
Depending on the model selected, our products support between 37 and 66 major languages and regional dialects, including English (US, UK, Australian, Indian accents), Spanish (Castilian and Latin American), French, German, Japanese, Arabic, Russian, Portuguese, and Mandarin.
Rather than using generic robotic text-to-speech, we implement neural child-friendly voice profiles calibrated for warm storytelling cadences, dramatic pauses, and correct tonal inflections tailored to each language's natural storytelling traditions.
For standard models in stock, our MOQ is as low as 1 piece to allow rapid physical evaluation, functional verification, and acoustic testing. For minor customization (such as silk-screened brand logos, custom retail packaging, or pre-flashed localized system greetings), our MOQ typically starts at 500 to 1,000 units.
Full OEM/ODM projects (involving proprietary plush skin creation, custom plastic mold injection tooling, and bespoke companion mobile app development) require an initial run of 2,000 to 3,000 units. Standard prototype samples ship within 3 to 7 working days, while customized production runs take approximately 25 to 35 business days.
All export products manufactured by Shenzhen Vgoodtoys Technology Co., Ltd. are engineered to pass comprehensive global compliance frameworks. Standard documentation includes CE (EMC, RED, LVD directives), FCC ID certification for North America, and RoHS environmental compliance.
For plush items, full physical and mechanical safety reports (EN71 Parts 1, 2, and 3 for the European Union; ASTM F963 and CPSIA for the United States) are available, verifying that textiles, small parts, battery compartments, and sound output levels strictly comply with international child safety mandates.
From initial acoustic prototyping to global port delivery, our experienced B2B engineering and sales managers work with you at every stage. We handle compliance documentation, factory inspections, and custom firmware adaptation.